Reinforcement learning · team project
Learning from demonstrations, then from play
A Rocket League research pipeline connecting demonstration pretraining, PPO self-play and controlled evaluation.
Getting a policy off the ground
Learning a game entirely through trial and error can spend a great deal of time on the basics. This project studied how demonstrations and teacher guidance interact with reinforcement learning.
What we built
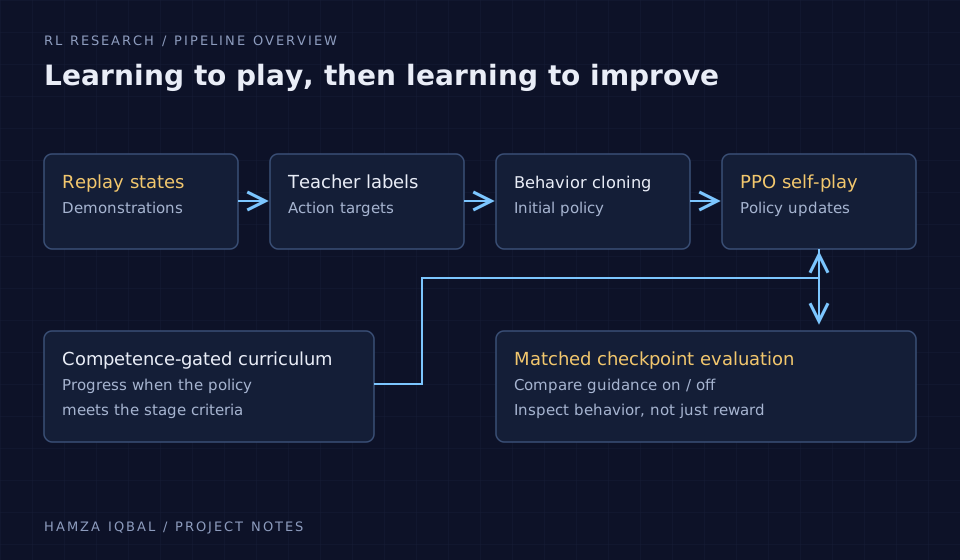
With SeongJun Kwon and James Edwardsen, I worked on a pipeline that pretrains a policy from teacher-labeled replay states, then continues learning through PPO self-play.
- Behavior-cloning pretraining to give the policy an initial action model.
- A competence-gated curriculum that ties progression to what the policy can do.
- Controlled teacher-guidance ablations, matched checkpoint evaluation and behavior diagnostics.
Beyond a reward curve
The evaluation work asks how an agent behaves and whether comparisons are made under the same conditions. That distinction matters when a training change improves a score without improving the behavior you wanted.
← All projects