LLM evaluation · public code
When retrieval helps
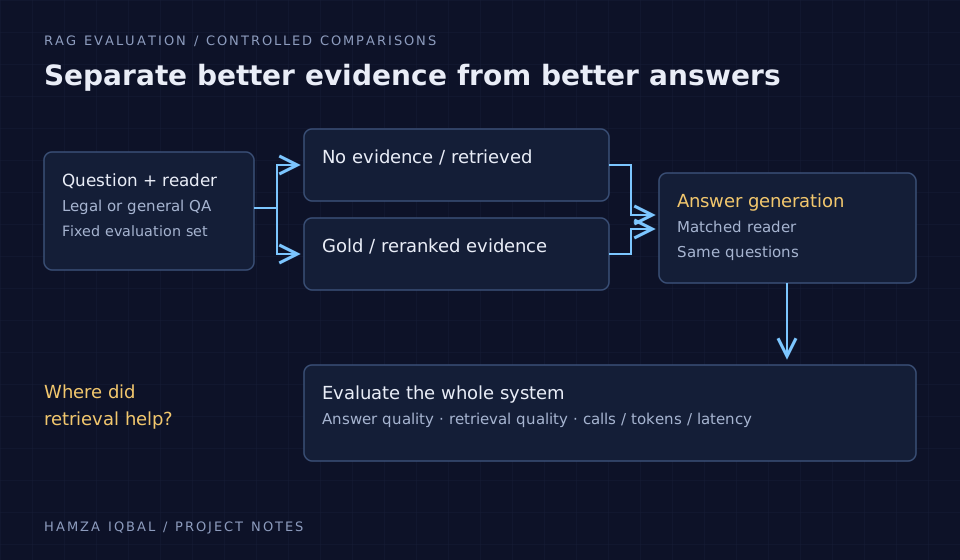
A multi-model QA harness that separates retrieval quality from answer accuracy and tracks the cost of each question.
Projects
Model training, careful evaluation, and interfaces that make complex systems easier to use. A selection of research, engineering and personal work.
A multi-model QA harness that separates retrieval quality from answer accuracy and tracks the cost of each question.
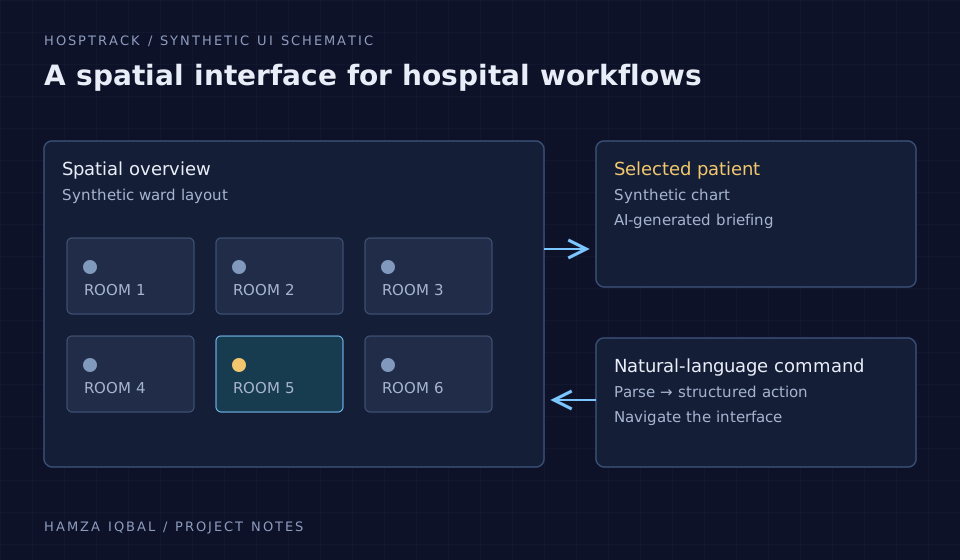
A spatial hospital-workflow prototype with AI chart briefings and natural-language navigation across synthetic records.
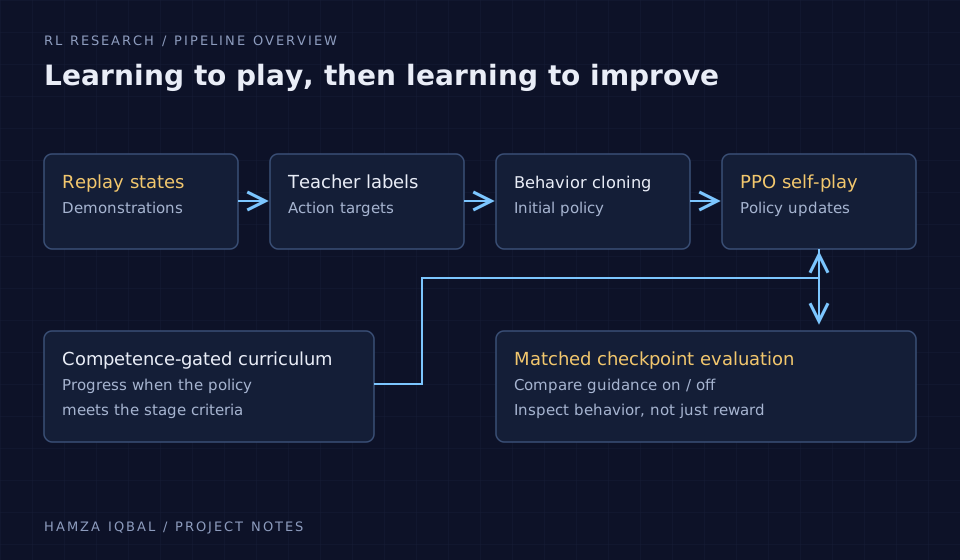
A Rocket League pipeline for behavior-cloning pretraining, PPO self-play and controlled teacher-guidance experiments.
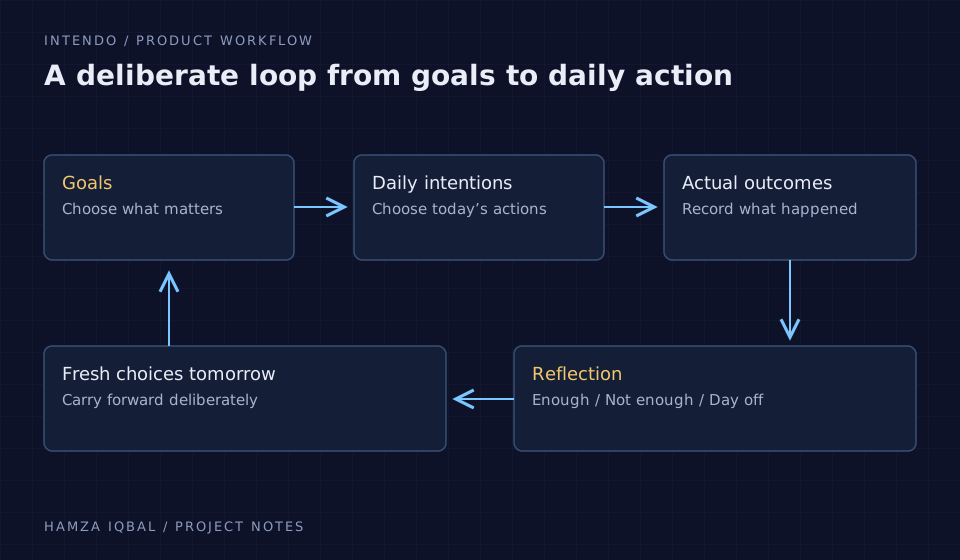
A deliberate daily planner with transactional history, revision-checked saves and an agent CLI that previews and verifies changes.
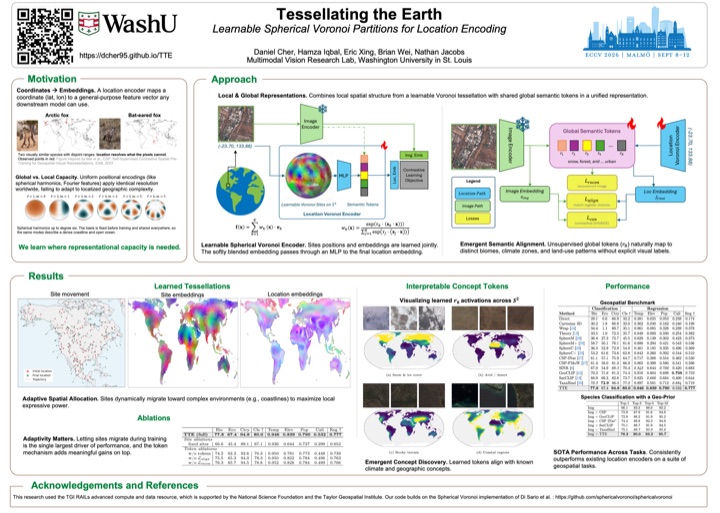
A location encoder with learnable spherical partitions. Co-authored research with public code and pretrained weights.
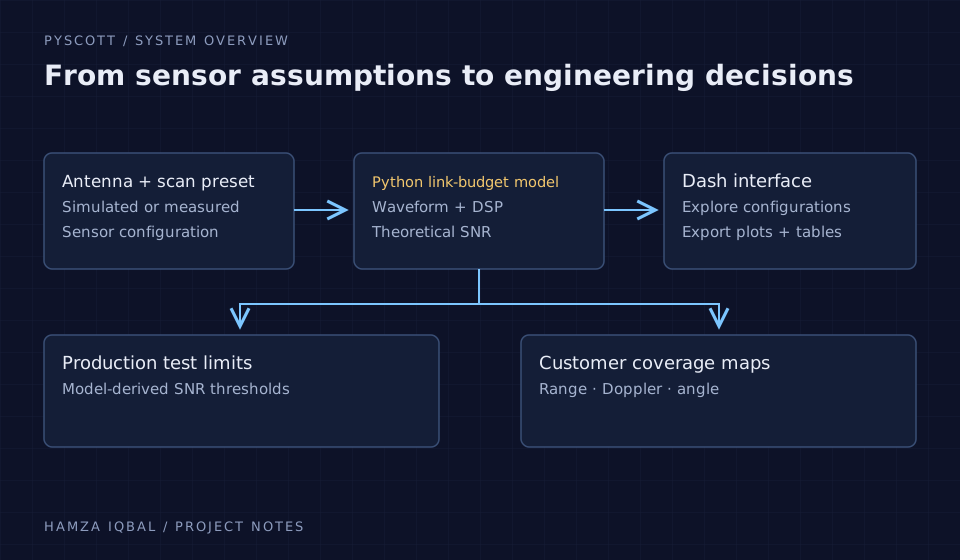
A Python/Dash modeling tool whose predictions informed production test limits and customer coverage maps.
Research and engineering for efficient image geolocalization: model training, embedding caches, budget-aware search and reproducible evaluation. Title, code and results remain withheld during review.
Public funding, publication and patent data assembled into university benchmarks, embedding-based research clusters and automated reports.
Spark ETL connecting HL7v2 lab results, FHIR resources and EMR records in PostgreSQL and MongoDB, with Apache Superset for exploration.
A Python/C and Arduino control system with a custom PCB: 85% lower cost and 87.5% lower latency than the commercial alternative. Presented at SfN and ABRCMS 2019.
Experiments on internal representations in mathematical reasoning.
Code →A training exercise spanning data preparation, tokenization, the training loop and evaluation.
Coursework deployed on AWS and GCP to explore hosting, storage and backend development.